

ChatGPT CLI is a powerful, multi-provider command-line interface for working with modern LLMs. It supports OpenAI,
Azure, Perplexity, LLaMA, and more, and includes streaming, interactive chat, prompt files, image/audio I/O, MCP tool
calls, and an experimental agent mode for multi-step tasks with safety and budget controls.
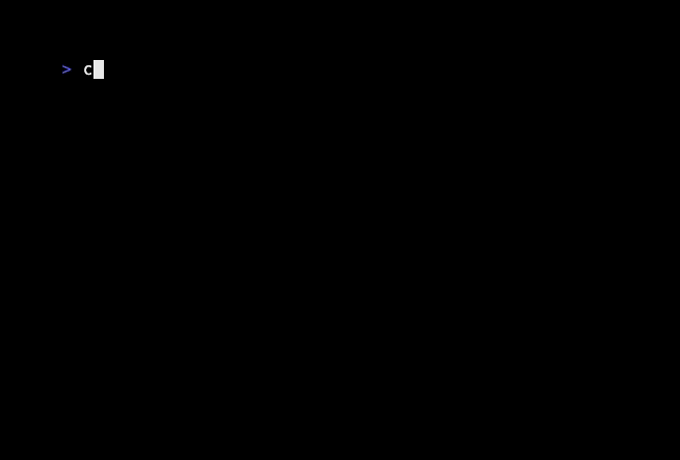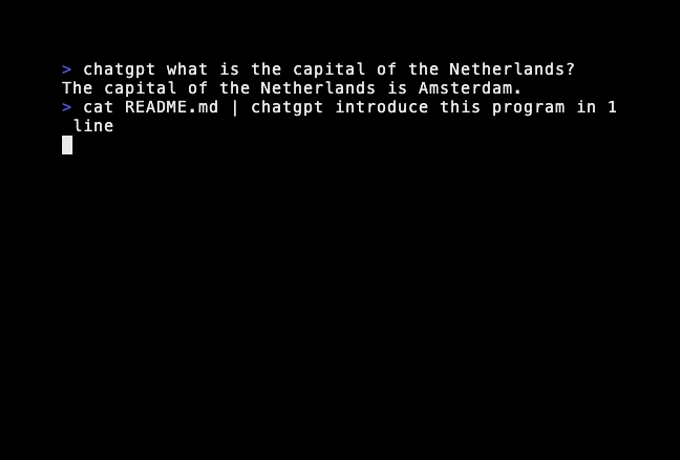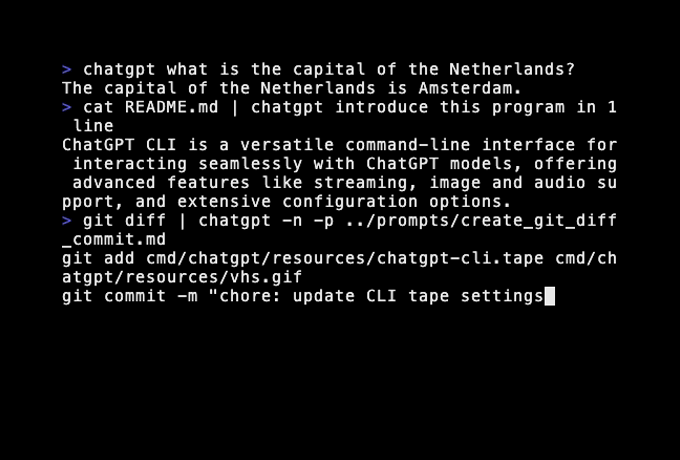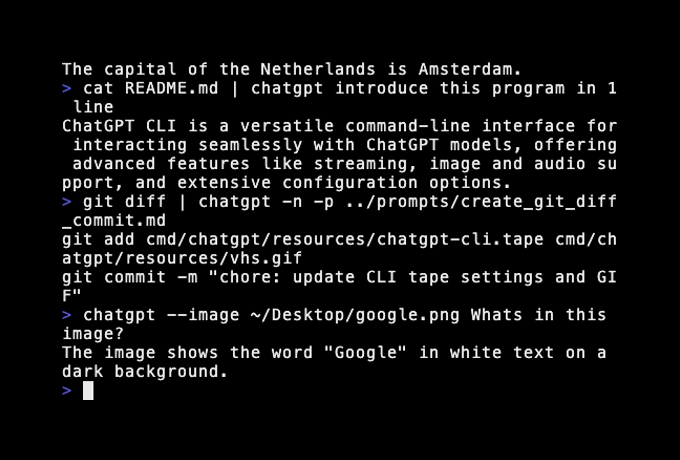
- Streaming mode: Real-time interaction with the GPT model.
- Query mode: Single input-output interactions with the GPT model.
- Interactive mode: The interactive mode allows for a more conversational experience with the model. Prints the
token usage when combined with query mode.
- Thread-based context management: Enjoy seamless conversations with the GPT model with individualized context for
each thread, much like your experience on the OpenAI website. Each unique thread has its own history, ensuring
relevant and coherent responses across different chat instances.
- Sliding window history: To stay within token limits, the chat history automatically trims while still preserving
the necessary context. The size of this window can be adjusted through the
context-window setting.
- Custom context from any source: You can provide the GPT model with a custom context during conversation. This
context can be piped in from any source, such as local files, standard input, or even another program. This
flexibility allows the model to adapt to a wide range of conversational scenarios.
- Agent mode (ReAct + Plan/Execute): Run multi-step tasks that can think, act, and observe using tools like shell,
file operations, and LLM reasoning. Supports both iterative ReAct loops and Plan/Execute workflows, with built-in *
budget limits* (time, steps, tokens) and policy enforcement (allowed tools, denied commands, workdir
sandboxing) for safe-by-default automation.
- Web search: Allow compatible models (e.g.
gpt-5+) to fetch live web data during a query. Enable with the web
setting and tune results using web_context_size.
- MCP (Model Context Protocol) support: Call external MCP tools via HTTP(S) or STDIO, inject their results into the
conversation context, and continue the prompt seamlessly.
- MCP session management: Built-in support for stateful MCP servers. The CLI automatically initializes
sessions, attaches session identifiers, and renews them when they become invalid.
- Support for images: Upload an image or provide an image URL using the
--image flag. Note that image support may
not be available for all models. You can also pipe an image directly: pngpaste - | chatgpt "What is this photo?"
- Generate images: Use the
--draw and --output flags to generate an image from a prompt (requires image-capable
models like gpt-image-1).
- Edit images: Use the
--draw flag with --image and --output to modify an existing image using a prompt (
e.g., "add sunglasses to the cat"). Supported formats: PNG, JPEG, and WebP.
- Audio support: You can upload audio files using the
--audio flag to ask questions about spoken content.
This feature is compatible only with audio-capable models like gpt-4o-audio-preview. Currently, only .mp3 and .wav
formats are supported.
- Transcription support: You can also use the
--transcribe flag to generate a transcript of the uploaded audio.
This uses OpenAI’s transcription endpoint (compatible with models like gpt-4o-transcribe) and supports a wider range
of formats, including .mp3, .mp4, .mpeg, .mpga, .m4a, .wav, and .webm.
- Text-to-speech support: Use the
--speak and --output flags to convert text to speech (works with models like
gpt-4o-mini-tts).
If you have afplay installed (macOS), you can even chain playback like this:
chatgpt --speak "convert this to audio" --output test.mp3 && afplay test.mp3
- Model listing: Access a list of available models using the
-l or --list-models flag.
- Advanced configuration options: The CLI supports a layered configuration system where settings can be specified
through default values, a
config.yaml file, and environment variables. For quick adjustments,
various --set-<value> flags are provided. To verify your current settings, use the --config or -c flag.
We’re excited to introduce support for prompt files with the --prompt flag in version 1.7.1! This feature
allows you to provide a rich and detailed context for your conversations directly from a file.
The --prompt flag lets you specify a file containing the initial context or instructions for your ChatGPT
conversation. This is especially useful when you have detailed instructions or context that you want to reuse across
different conversations.
To use the --prompt flag, pass the path of your prompt file like this:
chatgpt --prompt path/to/your/prompt.md "Use a pipe or provide a query here"
The contents of prompt.md will be read and used as the initial context for the conversation, while the query you
provide directly will serve as the specific question or task you want to address.
Here’s a fun example where you can use the output of a git diff command as a prompt:
git diff | chatgpt --prompt ../prompts/write_pull-request.md
In this example, the content from the write_pull-request.md prompt file is used to guide the model's response based on
the diff data from git diff.
For a variety of ready-to-use prompts, check out this awesome prompts repository.
These can serve as great starting points or inspiration for your own custom prompts!
Agent Mode (ReAct + Plan/Execute)
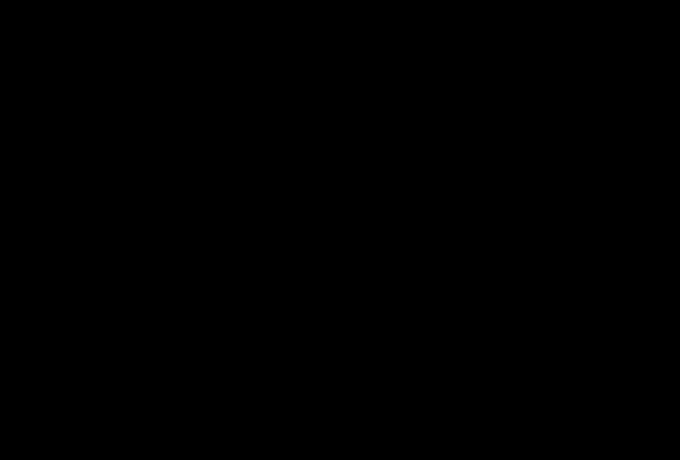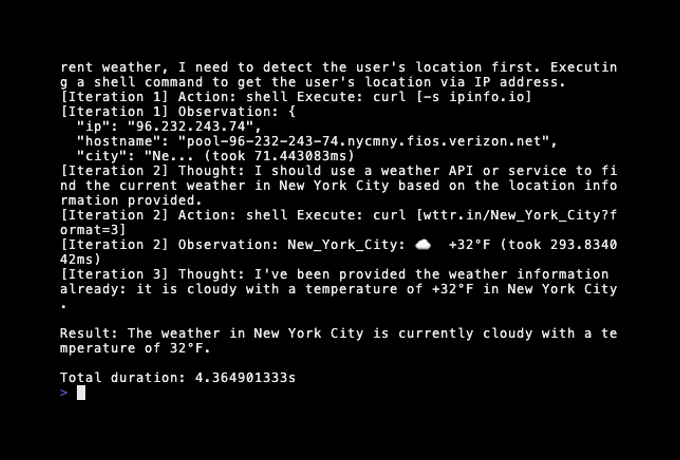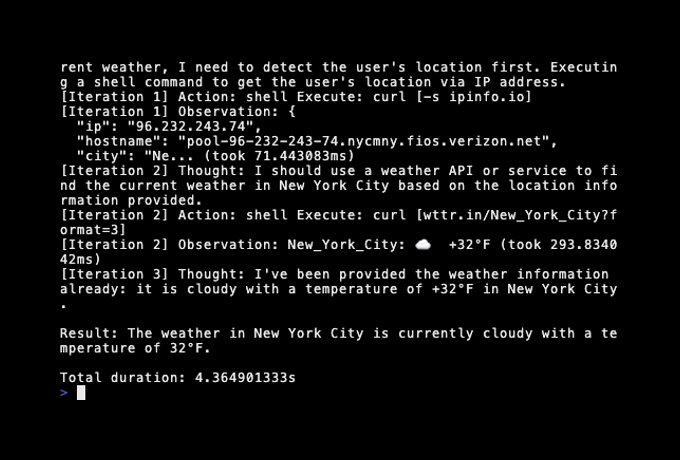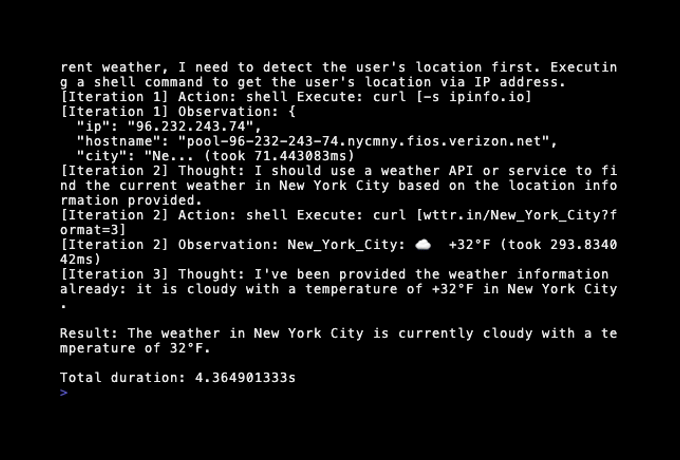
ChatGPT CLI includes an experimental agent mode that can plan and run multi-step tasks using tools (shell, file ops,
and LLM reasoning), while enforcing budget + policy constraints.
There are two agent modes:
- ReAct (-agent-mode react): iterative “think → act → observe” loop
- Plan/Execute (-agent-mode plan): generates a plan first, then executes it step-by-step
ReAct mode (default):
chatgpt why is my test failing? --agent
Plan/Execute mode:
chatgpt what is the weather like in brooklyn --agent --agent-mode plan
Agent file access can be restricted to a working directory. This is useful to prevent accidental reads/writes outside a
project.
chatgpt "what files are in the /tmp directory" \
  --agent \
  --agent-work-dir .
If a step tries to read/write outside the workdir, it will be denied by policy (e.g. kind=path_escape).
Agent execution is governed by:
- Budget limits (iterations, steps, tool calls, wall-time, token usage)
- Policy rules (allowed tools, denied shell commands, file op allowlist, and workdir path restrictions)
This keeps the agent useful while still being safe-by-default.
When running in agent mode, ChatGPT CLI automatically writes detailed execution logs to the cache directory, under:
$OPENAI_CACHE_HOME/agent/
These logs include:
- Planner output (for Plan/Execute mode)
- Tool calls and their results
- Timing and budget usage
- Debug-level traces when debug logging is enabled
Each agent run gets its own timestamped log directory, making it easy to inspect what happened after the fact or debug
unexpected behavior.
This is especially useful when:
- An agent run fails due to budget or policy limits
- You want to understand why the agent chose certain steps
- You’re developing or tuning agent policies and budgets
ChatGPT CLI supports the Model Context Protocol (MCP) over HTTP(S). This allows the CLI to call an MCP tool, inject the
tool’s result into the current thread as context, and then run your prompt — all in one command. The integration is
provider-agnostic.
You provide:
- MCP endpoint URL (
--mcp)
- Tool name (
--mcp-tool)
- Optional HTTP headers (
--mcp-header)
- Tool arguments (
--mcp-param or --mcp-params)
When --mcp is set, the CLI will:
- POST a JSON-RPC
tools/call request to your MCP server
- Automatically initialize and manage an MCP session if required
- Extract the tool output
- Store it as an assistant message in the active thread (prefixed with
[MCP: <tool>])
- Submit your query to the model (if you provided one)
Local FastMCP echo server (minimal MCP HTTP example):
chatgpt \
  --mcp "http://127.0.0.1:8000/mcp" \
  --mcp-tool echo \
  --mcp-param 'payload={"foo":"bar","count":3,"enabled":true}' \
  "What did the MCP server receive?"
Apify MCP example (production MCP server):
chatgpt \
  --mcp "https://mcp.apify.com/?tools=epctex/weather-scraper" \
  --mcp-tool "epctex-slash-weather-scraper" \
  --mcp-header "Authorization: Bearer $APIFY_API_KEY" \
  --mcp-param locations='["Brooklyn, NY"]' \
  --mcp-param timeFrame=today \
  --mcp-param units=imperial \
  --mcp-param proxyConfiguration='{"useApifyProxy":true}' \
  --mcp-param maxItems=1 \
  "what should I wear today"
Using --mcp-params (raw JSON) instead of multiple --mcp-param flags:
chatgpt \
  --mcp "https://your-mcp-server.example.com" \
  --mcp-tool "some-tool-name" \
  --mcp-params '{"locations":["Brooklyn, NY"],"timeFrame":"today"}' \
  "what should I wear today"
Local MCP server over stdio (no HTTP, runs as a subprocess):
chatgpt \
  --mcp "stdio:python test/mcp/stdio/mcp_stdio_server.py" \
  --mcp-tool echo \
  --mcp-param 'payload={"foo":"bar","count":3}' \
  "What did the MCP server receive?"
Headers and Authentication
MCP does not mandate a specific authentication mechanism. Some servers use Bearer tokens, others use API keys, cookies,
or no auth at all. Use --mcp-header to pass whatever your MCP server requires:
--mcp-header "Authorization: Bearer $TOKEN"
--mcp-header "X-Api-Key: $API_KEY"
Some MCP servers require a session identifier (commonly mcp-session-id) to be established before tool calls are
accepted. The ChatGPT CLI automatically manages MCP sessions for HTTP(S) servers that require them:
- Initializes a session when needed
- Caches the session identifier per endpoint
- Attaches it to subsequent requests
- Automatically re-initializes the session if the server invalidates it
Stateless servers are also supported: if initialize returns no mcp-session-id header, the CLI proceeds without one
(the streamable-HTTP spec makes the session id optional) rather than failing.
You can explicitly pass a session header yourself using --mcp-header. If you do, the CLI will respect it and skip
automatic session handling.
Tool results are injected into the conversation thread as context before your query runs. The injected message is stored
as an assistant message and prefixed like this:
If you run MCP without providing a query, the CLI will inject the context and exit:
chatgpt \
  --mcp "https://your-mcp-server.example.com" \
  --mcp-tool "some-tool-name" \
--mcp-params '{"foo":"bar"}'You can install chatgpt-cli using Homebrew:
brew tap kardolus/chatgpt-cli
brew trust kardolus/chatgpt-cli
brew install chatgpt-cli
Note: Homebrew 6.0+ requires you to explicitly trust third-party taps before
their formulae will run, so the brew trust step above is required (a one-time
action per machine). If you're upgrading and see
Refusing to load formula ... from untrusted tap, run
brew trust kardolus/chatgpt-cli and then brew upgrade chatgpt-cli.
For a quick and easy installation without compiling, you can directly download the pre-built binary for your operating
system and architecture:
curl -L -o chatgpt https://github.com/kardolus/chatgpt-cli/releases/latest/download/chatgpt-darwin-arm64 && chmod +x chatgpt && sudo mv chatgpt /usr/local/bin/
curl -L -o chatgpt https://github.com/kardolus/chatgpt-cli/releases/latest/download/chatgpt-darwin-amd64 && chmod +x chatgpt && sudo mv chatgpt /usr/local/bin/
curl -L -o chatgpt https://github.com/kardolus/chatgpt-cli/releases/latest/download/chatgpt-linux-amd64 && chmod +x chatgpt && sudo mv chatgpt /usr/local/bin/
curl -L -o chatgpt https://github.com/kardolus/chatgpt-cli/releases/latest/download/chatgpt-linux-arm64 && chmod +x chatgpt && sudo mv chatgpt /usr/local/bin/
curl -L -o chatgpt https://github.com/kardolus/chatgpt-cli/releases/latest/download/chatgpt-linux-386 && chmod +x chatgpt && sudo mv chatgpt /usr/local/bin/
curl -L -o chatgpt https://github.com/kardolus/chatgpt-cli/releases/latest/download/chatgpt-freebsd-amd64 && chmod +x chatgpt && sudo mv chatgpt /usr/local/bin/
curl -L -o chatgpt https://github.com/kardolus/chatgpt-cli/releases/latest/download/chatgpt-freebsd-arm64 && chmod +x chatgpt && sudo mv chatgpt /usr/local/bin/
Download the binary
from this link and add it
to your PATH.
Choose the appropriate command for your system, which will download the binary, make it executable, and move it to your
/usr/local/bin directory (or %PATH% on Windows) for easy access.
-
Set the OPENAI_API_KEY environment variable to
your ChatGPT secret key. To set the environment variable, you can add
the following line to your shell profile (e.g., ~/.bashrc, ~/.zshrc, or ~/.bash_profile), replacing your_api_key with
your actual key:
export OPENAI_API_KEY="your_api_key"
-
To enable history tracking across CLI calls, create a ~/.chatgpt-cli directory using the command:
Once this directory is in place, the CLI automatically manages the message history for each "thread" you converse
with. The history operates like a sliding window, maintaining context up to a configurable token maximum. This
ensures a balance between maintaining conversation context and achieving optimal performance.
By default, if a specific thread is not provided by the user, the CLI uses the default thread and stores the history
at ~/.chatgpt-cli/history/default.json. You can find more details about how to configure the thread parameter in
the
Configuration section of this document.
-
Try it out:
chatgpt what is the capital of the Netherlands
-
To start interactive mode, use the -i or --interactive flag:
If you want the CLI to automatically create a new thread for each session, ensure that the auto_create_new_thread
configuration variable is set to true. This will create a unique thread identifier for each interactive session.
-
To use the pipe feature, create a text file containing some context. For example, create a file named context.txt
with the following content:
Kya is a playful dog who loves swimming and playing fetch.
Then, use the pipe feature to provide this context to ChatGPT:
cat context.txt | chatgpt "What kind of toy would Kya enjoy?"
-
To list all available models, use the -l or --list-models flag:
-
For more options, see:
The ChatGPT CLI adopts a four-tier configuration strategy, with different levels of precedence assigned to flags,
environment variables, a config.yaml file, and default values, in that respective order:
- Flags: Command-line flags have the highest precedence. Any value provided through a flag will override other
configurations.
- Environment Variables: If a setting is not specified by a flag, the corresponding environment variable (prefixed with
the name field from the config) will be checked.
- Config file (config.yaml): If neither a flag nor an environment variable is set, the value from the config.yaml file
will be used.
- Default Values: If no value is specified through flags, config.yaml, or environment variables, the CLI will fall back
to its built-in default values.
| Variable |
Description |
Default |
name |
The prefix for environment variable overrides. |
'openai' |
thread |
The name of the current chat thread. Each unique thread name has its own context. |
'default' |
target |
Load configuration from config.target.yaml |
'' |
omit_history |
If true, the chat history will not be used to provide context for the GPT model. |
false |
command_prompt |
The command prompt in interactive mode. Should be single-quoted. |
'[%datetime] [Q%counter]' |
output_prompt |
The output prompt in interactive mode. Should be single-quoted. |
'' |
command_prompt_color |
The color of the command_prompt in interactive mode. Supported colors: "red", "green", "blue", "yellow", "magenta". |
'' |
output_prompt_color |
The color of the output_prompt in interactive mode. Supported colors: "red", "green", "blue", "yellow", "magenta". |
'' |
auto_create_new_thread |
If set to true, a new thread with a unique identifier (e.g., int_a1b2) will be created for each interactive session. If false, the CLI will use the thread specified by the thread parameter. |
false |
auto_shell_title |
If set to true, sets the title of the shell to the name of the current thread. |
false |
track_token_usage |
If set to true, displays the total token usage after each query in --query mode, helping you monitor API usage. |
false |
debug |
If set to true, prints the raw request and response data during API calls, useful for debugging. |
false |
custom_headers |
Add a map of custom headers to each http request |
{} |
skip_tls_verify |
If set to true, skips TLS certificate verification, allowing insecure HTTPS requests. |
false |
http_timeout |
HTTP client timeout in seconds. Set to 0 for no timeout, useful for slow or local models. |
60 |
max_retries |
Number of times to retry a request that fails with a connection error, 429, or 5xx status. A positive Retry-After header is honored; otherwise exponential backoff with jitter is used. 0 keeps the built-in default of 3; a negative value disables retries. Retries only re-establish the request, never mid-stream. Note: a retried completion POST can be processed twice server-side if the first response was lost after the request was received (same trade-off the official SDKs make). |
3 |
retry_base_delay_ms |
Base delay in milliseconds for exponential backoff between retries (ignored when the server sends a Retry-After header). |
500 |
multiline |
If set to true, enables multiline input mode in interactive sessions. |
false |
role_file |
Path to a file that overrides the system role (role). |
'' |
prompt |
Path to a file that provides additional context before the query. |
'' |
image |
Local path or URL to an image used in the query. |
'' |
audio |
Path to an audio file (MP3/WAV) used as part of the query. |
'' |
output |
Path where synthesized audio is saved when using --speak. |
'' |
transcribe |
Enables transcription mode. This flags takes the path of an audio file. |
false |
speak |
If true, enables text-to-speech synthesis for the input query. |
false |
draw |
If true, generates an image from a prompt and saves it to the path specified by output. Requires image-capable models. |
false |
web |
Enable web search for supported models (e.g. gpt-5+). |
false |
web_context_size |
Controls how much context is retrieved during web search (low, medium, high). |
low |
LLM-Specific Configuration
| Variable |
Description |
Default |
api_key |
Your API key. |
'' |
api_key_file |
Load the API key from a file instead of the environment. Takes precedence over the environment variable. |
'' |
auth_header |
The header used for authorization in API requests. |
'Authorization' |
auth_token_prefix |
The prefix to be added before the token in the auth_header. |
'Bearer ' |
completions_path |
The API endpoint for completions. |
'/v1/chat/completions' |
context_window |
The memory limit for how much of the conversation can be remembered at one time. |
8192 |
effort |
Sets the reasoning effort. Used by gpt-5 and o1-pro models. |
'low' |
frequency_penalty |
Number between -2.0 and 2.0. Positive values penalize new tokens based on their existing frequency in the text so far. |
0.0 |
image_edits_path |
The API endpoint for image editing. |
'/v1/images/edits' |
image_generations_path |
The API endpoint for image generation. |
'/v1/images/generations' |
max_tokens |
The maximum number of tokens that can be used in a single API call. |
4096 |
model |
The GPT model used by the application. |
'gpt-4o' |
models_path |
The API endpoint for accessing model information. |
'/v1/models' |
presence_penalty |
Number between -2.0 and 2.0. Positive values penalize new tokens based on whether they appear in the text so far. |
0.0 |
responses_path |
The API endpoint for responses. Used by o1-pro models. |
'/v1/responses' |
role |
The system role |
'You are a helpful assistant.' |
seed |
Sets the seed for deterministic sampling (Beta). Repeated requests with the same seed and parameters aim to return the same result. |
0 |
speech_path |
The API endpoint for text-to-speech synthesis. |
'/v1/audio/speech' |
temperature |
What sampling temperature to use, between 0 and 2. Higher values make the output more random; lower values make it more focused and deterministic. |
1.0 |
top_p |
An alternative to sampling with temperature, called nucleus sampling, where the model considers the results of the tokens with top_p probability mass. |
1.0 |
transcriptions_path |
The API endpoint for audio transcription requests. |
'/v1/audio/transcriptions' |
url |
The base URL for the API — origin only (scheme + host). The *_path values are appended to it, so don't include /v1 here or requests will 404 with a doubled prefix (e.g. use url: https://my-host + completions_path: /v1/chat/completions). |
'https://api.openai.com' |
user_agent |
The header used for the user agent in API requests. |
'chatgpt-cli' |
voice |
The voice to use when generating audio with TTS models like gpt-4o-mini-tts. |
'nova' |
response_format |
Structured output for the Chat Completions API: json_object for JSON mode, or a JSON Schema string to constrain the output. Empty disables it. |
'' |
tools |
Enable model-driven function calling. The model can call tools advertised by the --mcp endpoint and the CLI feeds results back until it answers. |
false |
max_tool_calls |
Maximum number of tool-call rounds per query before giving up (guards against a model that keeps calling tools). 0 uses the built-in default of 10. |
10 |
Function calling & JSON mode
- JSON mode / structured output: pass
--json for plain JSON output
(shorthand for --response-format json_object), or --response-format '<schema>' / --response-format @schema.json to constrain output to a JSON
Schema. Also settable persistently via the response_format config. Note:
OpenAI's json_object mode requires your prompt to mention "JSON" somewhere,
otherwise the API rejects the request — phrase your request accordingly (a
JSON Schema via --response-format does not have this constraint).
- Function calling: pass
--tools together with --mcp <endpoint> to let
the model call that MCP server's tools autonomously. The CLI lists the
server's tools (tools/list), advertises them to the model, dispatches each
requested call (tools/call), and feeds the results back — looping until the
model produces a final answer (bounded by max_tool_calls). This is a step up
from the one-shot --mcp-tool context injection. Function calling forces
non-streaming (--query) mode, since a tool call must be received in full
before it can be dispatched.
| Variable |
Description |
Default |
agent |
Enable agent mode |
false |
agent.mode |
Strategy (react or plan) |
react |
agent.work_dir |
Working directory |
. |
agent.max_iterations |
Max ReAct iterations |
10 |
agent.max_steps |
Max plan steps |
10 |
agent.max_wall_time |
Max wall time (0 = unlimited) |
0 |
agent.max_shell_calls |
Max shell calls (0 = unlimited) |
0 |
agent.max_llm_calls |
Max LLM calls (0 = unlimited) |
10 |
agent.max_file_ops |
Max file ops (0 = unlimited) |
0 |
agent.max_llm_tokens |
Max LLM tokens (0 = unlimited) |
0 |
agent.allowed_tools |
Allowed tools |
see below |
agent.denied_shell_commands |
Denied shell commands |
see below |
agent.allowed_file_ops |
Allowed file ops |
see below |
agent.restrict_files_to_work_dir |
Sandbox to workdir |
true |
agent.write_plan_json |
Write plan.json in plan mode |
true |
agent.plan_json_path |
Override plan.json path |
"" |
agent.dry_run |
No side effects |
false |
You can also use flags, for example:
chatgpt "what files are here?" --agent --agent-work-dir /tmp
allowed_tools: [shell, llm, files]
denied_shell_commands: [rm, sudo, dd, mkfs, shutdown, reboot]
allowed_file_ops: [read, write]
Custom Config, Cache and Data Directory
By default, ChatGPT CLI stores configuration and history files in the ~/.chatgpt-cli directory. However, you can
easily override these locations by setting environment variables, allowing you to store configuration and history in
custom directories.
| Environment Variable |
Description |
Default Location |
OPENAI_CONFIG_HOME |
Overrides the default config directory path. |
~/.chatgpt-cli |
OPENAI_DATA_HOME |
Overrides the default data directory path. |
~/.chatgpt-cli/history |
OPENAI_CACHE_HOME |
Overrides the default cache directory path. |
~/.chatgpt-cli/cache |
Example for Custom Directories
To change the default configuration or data directories, set the appropriate environment variables:
export OPENAI_CONFIG_HOME="/custom/config/path"
export OPENAI_DATA_HOME="/custom/data/path"
export OPENAI_CACHE_HOME="/custom/cache/path"
If these environment variables are not set, the application defaults to ~/.chatgpt-cli for configuration files and ~
/.chatgpt-cli/history for history.
Switching Between Configurations with --target
You can maintain multiple configuration files side by side and switch between them using the --target flag. This is
especially useful if you use multiple LLM providers (like OpenAI, Perplexity, Azure, etc.) or have different contexts or
workflows that require distinct settings.
How it Works
When you use the --target flag, the CLI loads a config file named:
For example:
chatgpt --target perplexity --config
This will load:
~/.chatgpt-cli/config.perplexity.yaml
If the --target flag is not provided, the CLI falls back to:
~/.chatgpt-cli/config.yaml
Example Setup
You can maintain the following structure:
~/.chatgpt-cli/
├── config.yaml # Default (e.g., OpenAI)
├── config.perplexity.yaml # Perplexity setup
├── config.azure.yaml # Azure-specific config
└── config.llama.yaml # LLaMA setup
Then switch between them like so:
chatgpt --target azure "Explain Azure's GPT model differences"
chatgpt --target perplexity "What are some good restaurants in the Red Hook area"
Or just use the default:
chatgpt "What's the capital of Sweden?"
CLI and Environment Interaction
- The value of
--target is never persisted — it must be explicitly passed for each run.
- The config file corresponding to the target is loaded before any environment variable overrides are applied.
- Environment variables still follow the name: field inside the loaded config, so name: perplexity enables
PERPLEXITY_API_KEY.
Variables for interactive mode:
%date: The current date in the format YYYY-MM-DD.%time: The current time in the format HH:MM:SS.%datetime: The current date and time in the format YYYY-MM-DD HH:MM:SS.%counter: The total number of queries in the current session.%usage: The usage in total tokens used (only works in query mode).
The defaults can be overridden by providing your own values in the user configuration file. The structure of this file
mirrors that of the default configuration. For instance, to override
the model and max_tokens parameters, your file might look like this:
model: gpt-3.5-turbo-16k
max_tokens: 4096
This alters the model to gpt-3.5-turbo-16k and adjusts max_tokens to 4096. All other options, such as url
, completions_path, and models_path, can similarly be modified.
You can also add custom HTTP headers to all API requests. This is useful when working with proxies, API gateways, or
services that require additional headers:
custom_headers:
  X-Custom-Header: "custom-value"
  X-API-Version: "v2"
  X-Client-ID: "my-client-id"
If the user configuration file cannot be accessed or
is missing, the application will resort to the default configuration.
Another way to adjust values without manually editing the configuration file is by using environment variables.
The name attribute forms the prefix for these variables. As an example, the model can be modified using
the OPENAI_MODEL environment variable. Similarly, to disable history during the execution of a command, use:
OPENAI_OMIT_HISTORY=true chatgpt what is the capital of Denmark?
This approach is especially beneficial for temporary changes or for testing varying configurations.
Moreover, you can use the --config or -c flag to view the present configuration. This handy feature allows users to
swiftly verify their current settings without the need to manually inspect the configuration files.
Executing this command will display the active configuration, including any overrides instituted by environment
variables or the user configuration file.
To facilitate convenient adjustments, the ChatGPT CLI provides flags for swiftly modifying the model, thread
, context-window and max_tokens parameters in your user configured config.yaml. These flags are --set-model
, --set-thread, --set-context-window and --set-max-tokens.
For instance, to update the model, use the following command:


