✨PhoneCLI✨: Making ALL Mobile Apps Agent-Native
The bottleneck of phone agents was never model size. Nearly every GUI agent today runs the same loop — screenshot, call a vision-language model (VLM), emit an action. It is slow (2–5 s per step), expensive (every screenshot is an API call), brittle (VLMs hallucinate coordinates), and it has to be online: your screen leaves the device. That is at odds with what a phone is — on-device, real-time, private. And most of what that loop does is navigation, which is static, ordered, and repeated ten thousand times.
So we did not build a bigger model. We built the model and the harness together:
|
|
① 🖥 Harness
GUI + CLI, two modalities |
Offline, a BFS crawler compiles an app's navigation into a YAML app map, and every screen becomes one deterministic command. Online, those commands replay deterministically on the device — WebDriverAgent on iOS, ADB on Android — in sub-second time at zero VLM cost, while GUI mode handles screens the map has never seen. A failed CLI path falls back to GUI — so compilation can only help. |
② 📱 On-device first
one request, three tiers |
A request is served by CLI → on-device model → cloud: the CLI tier absorbs navigation at zero model cost, and only the remaining steps ever reach a model. End to end this cuts cloud calls by ~10%, and an efficient memory (10–20 steps of context) is what lets a single phone keep running. |
③ 🤖 Model
open and replaceable |
The CLI path needs no model at all, and the fallback path takes any model — a general LLM or a GUI-tuned one. The open 3B on-device model we ship is the engine, not the headline. |
What it buys, measured — AndroidLab, 9 apps / 138 tasks, Qwen3.7-Plus as the cloud model, one judge throughout:
- 63.0% vs 50.7% task success — +12.3 points over the pure-VLM loop.
- 7.52 → 6.72 steps (−11%) and 40.1k → 34.4k tokens (−14%) — same tasks, fewer model calls.
- 0 model calls to execute a compiled command: navigation replays deterministically, in sub-second time.
➜ Full iOS real-device documentation — setup, WebDriverAgent, app map building, CLI reference, troubleshooting.
➜ AndroidLab evaluation documentation — the official AndroidLab suite (9 apps / 138 tasks), one compiled app map per app, the macro agent and its pure-VLM baseline, and judging.
➜ PhoneCLI paper — arXiv:2609.35671 · OpenPhone paper — arXiv:2510.22009
➜ Read the method ↓ — app maps, the three stages, and why compilation can only help.
🎯 The Bottleneck Is Not Model Size
Almost every GUI agent today runs the same loop: screenshot → call a vision-language model (VLM) → emit an action. It works, but it is a poor fit for a phone:
|
|
| 🐌 Slow |
2–5 s per step — every step waits for a model |
| 💸 Expensive |
every screenshot is an API call |
| 🎲 Brittle |
VLMs hallucinate coordinates; one wrong tap derails the task |
| 🌐 Online-bound |
the screen has to leave the device, which rules out private, real-time use |
And most of what that loop does is navigation. Turning on Wi-Fi, opening today's calendar, finding a contact — these are fixed sequences, executed in the same order, thousands of times. Re-discovering them through a VLM on every run is the expensive part, and it is also the part that never changes. Where a deterministic path exists, the VLM loop is simply the wrong tool:
So the conclusion was not "train a bigger model". It was: compile navigation once, replay it deterministically, and keep the model for what is genuinely new. That is what PhoneCLI does — and the rest of this repository is the stack built around it.
🖥 PhoneCLI: From App Interfaces To Callable Commands For Mobile Agents
Instead of treating every task as a novel GUI exploration, PhoneCLI compiles an app's navigation into callable commands. Offline, it explores the app from the outside and records what it finds into an app map — screens, interactive elements, and the edges between them. Online, a task is routed to one of those commands and replayed deterministically; a model is consulted only for what is genuinely new, or to verify the result.
1. Build an app map — A BFS crawler systematically explores every screen of
an app via WebDriverAgent, recording all tappable elements, their coordinates,
and the navigation paths between screens. Each element is classified (stable vs.
dynamic) and enriched with semantic metadata by an LLM.
# The app map encodes every screen as a node, every element as an edge
screens:
  - id: screen_0
    description: "Settings main page"
    elements:
      - text: Wi-Fi
        center: [0.50, 0.15]      # normalized coordinates
        fixed: true                 # stable across app updates
        leads_to: screen_1          # where this tap navigates

screen_macros:
  screen_1: [force_stop, launch, tap(195, 126)]  # exact replay sequence
2. Run a task — The agent maps a natural language task to a macro operation
with a single text-only call (no screenshot), replays it deterministically,
then optionally verifies with one screenshot check. A routine task therefore
costs one text-only routing call plus at most one screenshot check — not one
VLM call per step.
3. Handle the unexpected — When a task doesn't match any macro (e.g. "Find
restaurants near me that are open late"), the agent falls back to pure VLM
reasoning. The system gracefully degrades to GUI mode only when needed.
4. Compose across apps — A task that spans several apps is decomposed into
single-app subtasks first, each served by its own app's map and commands
(run.py --app-map is repeatable for exactly this case).
The intuition is simple: don't ask a VLM to re-discover what you already
know. Pre-compute the navigation graph once, then replay it reliably forever.
This is the same principle that makes CLI tools faster than GUI — applied to
phone automation.
# 1. Build a map for any iOS app (~10 minutes, one-time)
python phonecli/cli.py macro auto-build -b com.apple.Preferences -a Settings

# 2. Run a task
python phonecli/run.py --task "Turn on airplane mode"

# 3. Interactive daemon (continuous multi-task session)
python phonecli/run.py --interactive
The package ships with pre-built maps for 8 apps (微博, foodpanda,
Calendar, 京东, Dianping, 小红书, Music, Settings). Each covers up to 50 screens
— 50 is the crawler's default cap — with 400–1,300 elements per app:
400 screens and 6,366 elements in total.
➜ Full iOS real-device documentation — setup, WebDriverAgent,
app map building, CLI reference, troubleshooting.
➜ AndroidLab evaluation documentation — the official
AndroidLab benchmark (9 apps / 138 tasks), compiled app maps, the macro agent and its
pure-VLM baseline, and judging.
📱 On-Device First: CLI → Device → Cloud
Each request is routed to the cheapest tier that can serve it, escalating only when that tier cannot:
- 🖥 CLI — if a compiled command covers the navigation part of the task, it runs on the device with zero model calls: deterministic, sub-second replay.
- 📱 On-device model — whatever the CLI path does not cover is handled by a local vision-language model, so no screen content has to leave the phone.
- ☁️ Cloud — only what the local model genuinely cannot do is escalated.
The route is chosen dynamically: task complexity is assessed at runtime, and execution re-routes between local and cloud as the run progresses and failures appear.
💾 Memory — what lets a phone keep going
Running long tasks on a phone is a memory problem before it is a model problem:
- Long-horizon reasoning — multi-step chain-of-thought with reflective error correction.
- Text-based summarization — screenshots are compressed into compact textual state instead of being carried as images.
- 10–20 steps of context retained inside a phone-sized token budget.
Left: how execution steps split between cloud and on-device models. Right: the resulting reduction in cloud API calls.
- Cloud still handles ~65% of the steps. Small on-device models cannot carry all of the reasoning — which is exactly why the CLI tier matters: it removes the navigation share of the work at zero model cost, before any model is consulted.
- ~10% fewer cloud API calls. Adding on-device execution to a cloud-only baseline cuts cloud invocations by roughly a tenth.
- Stronger cloud models need less help. Models such as GLM-4.5V show a smaller reduction in cloud dependency, because they finish more tasks unaided.
The CLI tier's own contribution is measured separately, on the AndroidLab suite — see the evaluation section below.
🤖 The Model: Open, Replaceable Engine
The CLI path needs no model at all, and the fallback path accepts any model — a general-purpose LLM/VLM, or a GUI-tuned one. PhoneCLI is a harness, not a model. We ship one engine because a phone is a tight deployment target, but swapping it is a configuration change rather than a rewrite.
We believe the future of mobile AI lies not in making models larger, but in making them deployable under real constraints:
- Hardware fit — 3B aligns with consumer GPU memory (8–12 GB) and emerging mobile-NPU budgets.
- Speed — 3–5× faster per step than 7B alternatives at competitive accuracy for sub-second GUI responses.
- Power — a smaller footprint extends battery life, which is what mobile deployment actually costs.
- Privacy — the model fits on the device, so a task can run without the screen leaving the phone.
- Performance — with the right training recipe, 3B reaches the range of 7B–9B models on GUI tasks.
- Synthetic data — advanced MLLMs generate reasoning-chain training data, sidestepping the scarcity of manual annotations.
- Two stages — SFT injects GUI fundamentals; GRPO-style RL then optimizes task-completion accuracy.
- Small-model boost — structured training is what lets a 3B model compete with 7B–9B models on GUI tasks.
Average inference time per step with vLLM. Note that GLM-4.1V-9B-Thinking could not run on a single 3090 because of context-length limits:
| Model |
GPUs |
Size |
SR |
Time Cost / Step |
| Qwen2.5-VL-7B-Instruct |
Single 3090 |
7B |
10.1 |
6289.15 ms |
| OpenPhone |
Single 3090 |
3B |
15.2 |
4170.63 ms |
| GLM-4.1V-9B-Thinking |
Two 3090s |
9B |
24.6 |
14584.89 ms |
| Qwen2.5-VL-7B-Instruct |
Two 3090s |
7B |
10.1 |
4587.79 ms |
| OpenPhone |
Two 3090s |
3B |
15.2 |
3524.25 ms |
- 3.5× faster than GLM-4.1V-9B-Thinking when OpenPhone runs on one 3090 while GLM needs two; 4× faster when both use two.
- The 9B model's inability to run on a single 3090 is precisely the deployment constraint that matters at the edge.
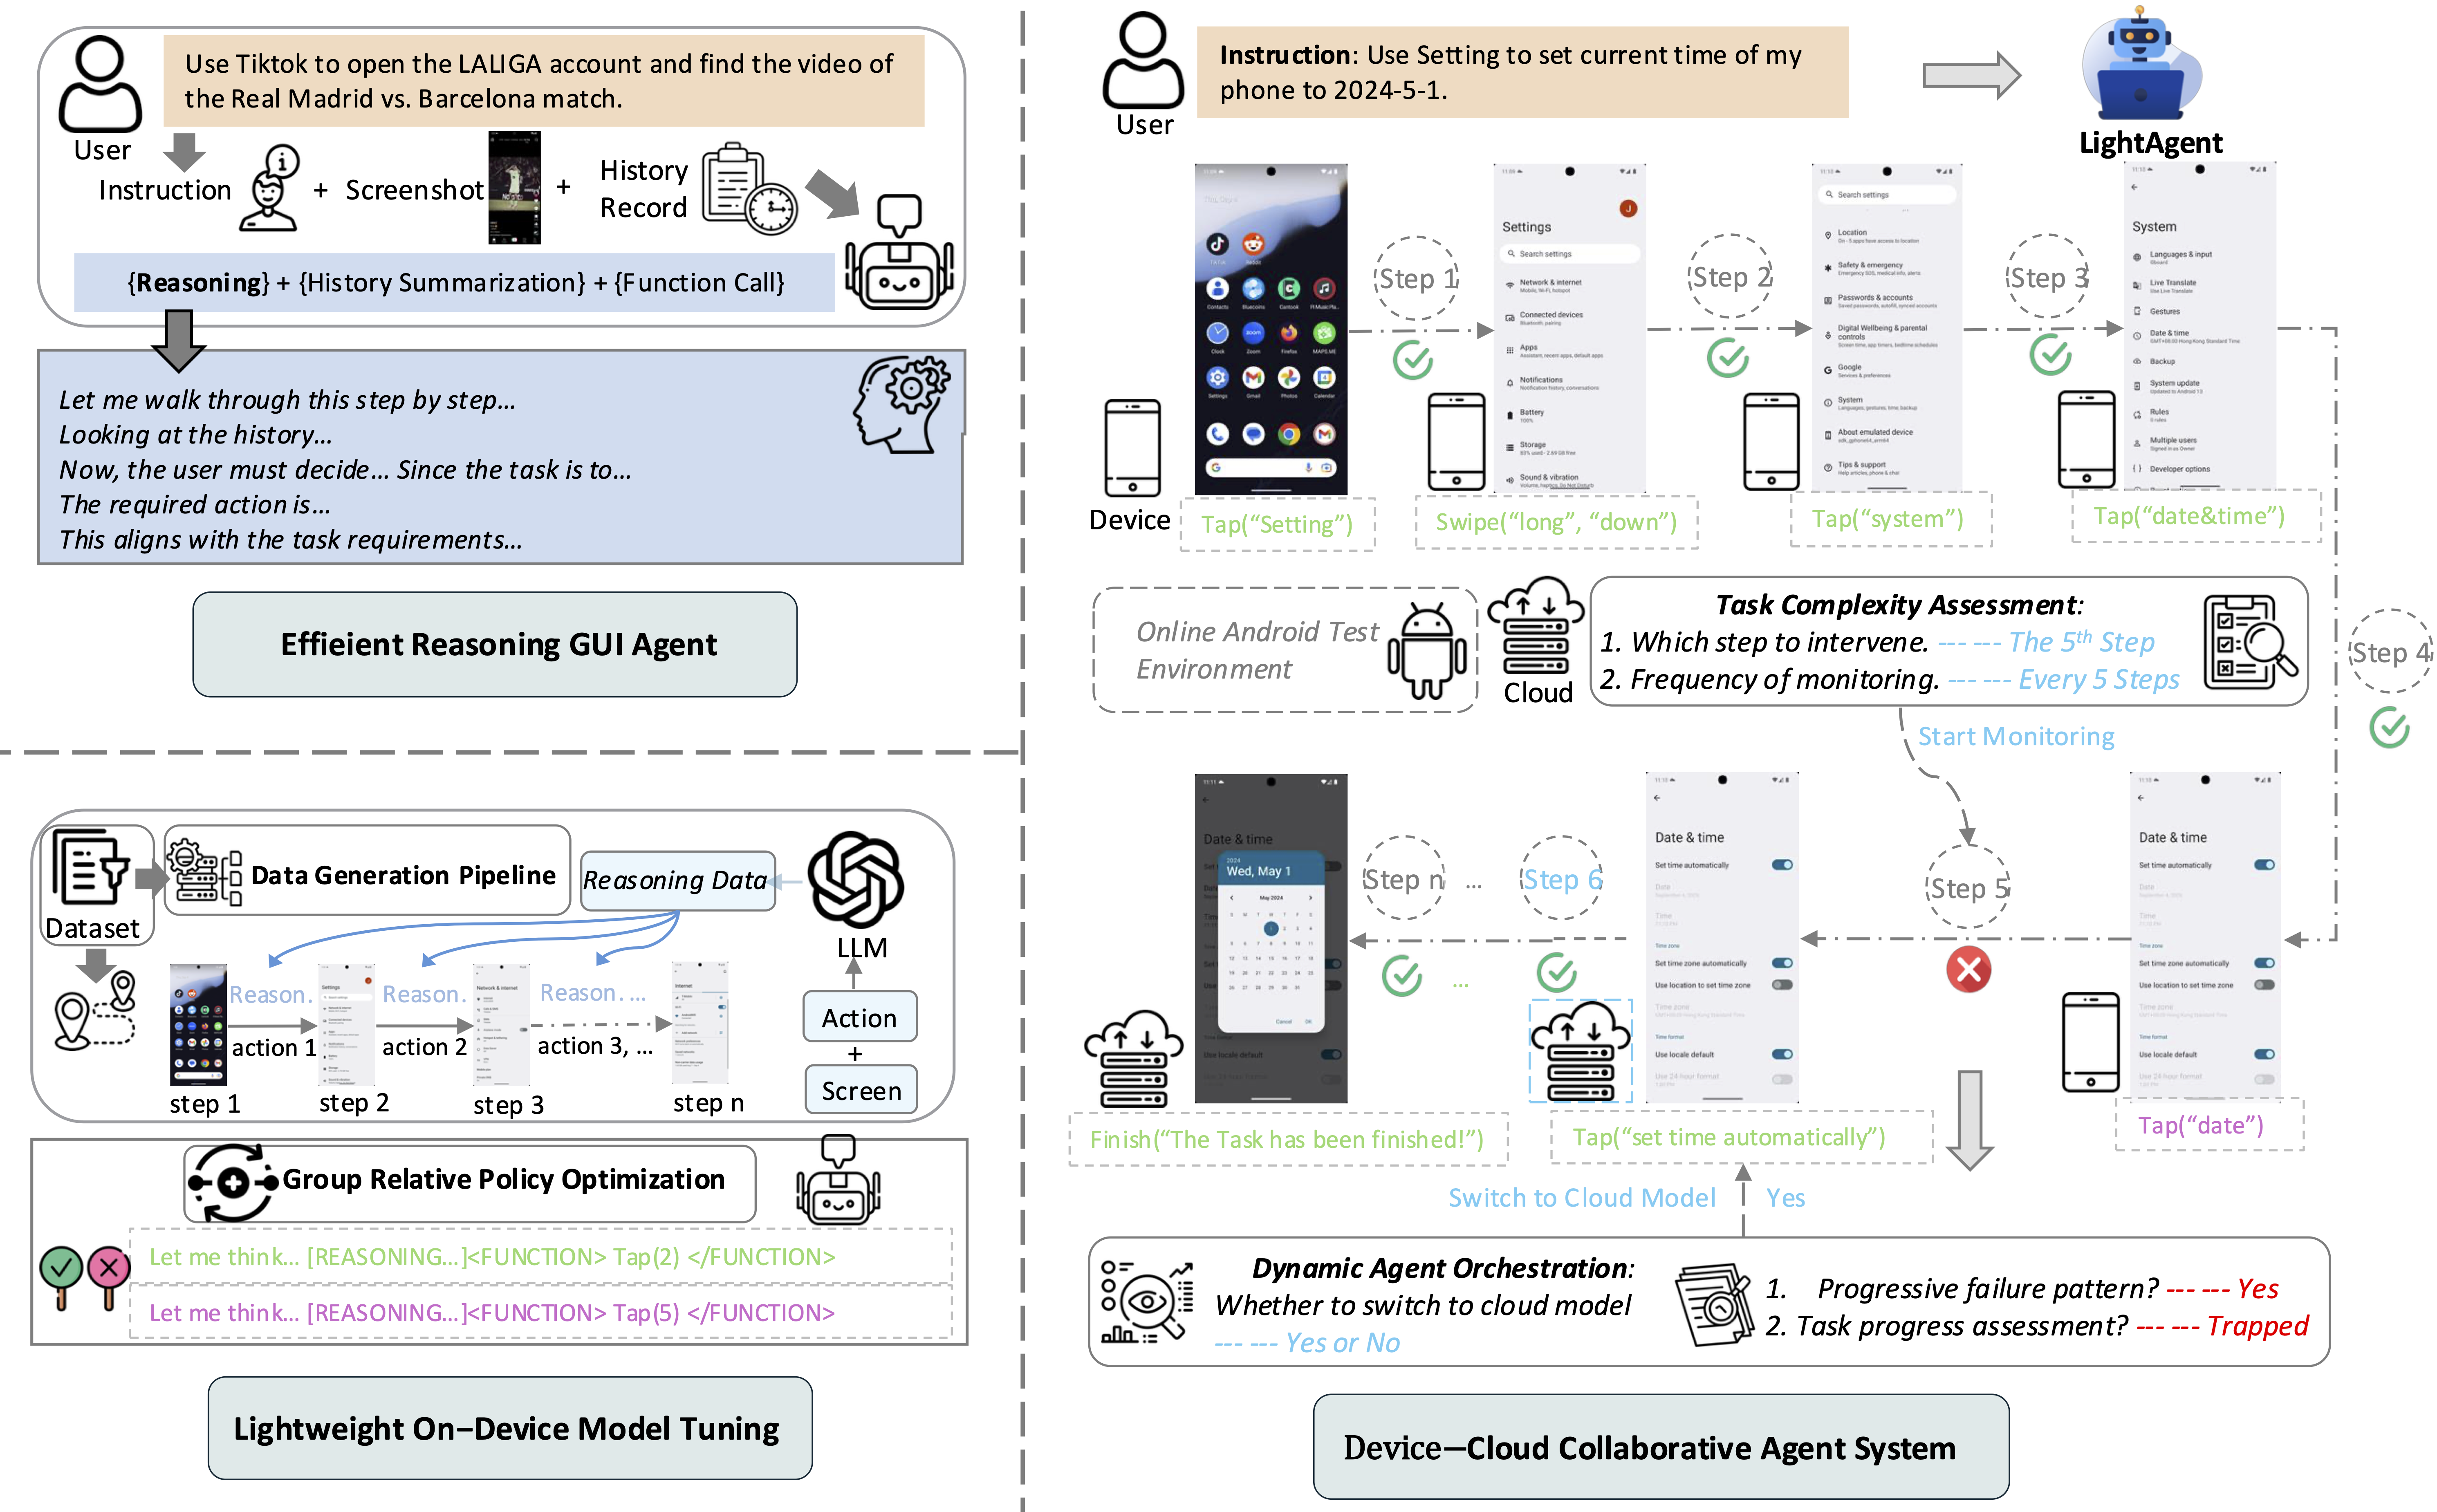
The repository is the stack described above:
Build a map and run a task (iOS) — the full walkthrough is in Get Started:
python phonecli/cli.py macro auto-build -b com.apple.Preferences -a Settings   # one-time, ~10 min
python phonecli/run.py --task "Turn on airplane mode"
Deploy the model (optional) — the CLI path does not need a model at all. Inference scripts live in vllm_script/: download the weights, serve them with vLLM, and point the agent config at the endpoint.
Credentials — the shipped example config runs against a local vLLM server (configs/example_xml_cloud_hyper.yaml, api_base: http://localhost:8002/v1), so it needs no key. Cloud configs read ${OPENROUTER_API_KEY} from the environment instead (export OPENROUTER_API_KEY=..., resolved by config_env.py). The legacy ScreenshotTask path still has three hardcoded placeholders in evaluation/evaluation.py (lines 63, 75, 81), and the LLM judge takes its key from evaluation/tasks/llm_evaluator.py (lines 10 and 12) or from generate_result.py --api_key.
Looking for the benchmark? Environment setup, batch scripts, judging and results all live in Evaluation.
📱 AndroidLab benchmark setup
Installation: follow the official AndroidLab documentation for complete setup instructions.
- Recommended mode: AVD on Mac (arm64) — the configuration validated in our experiments.
- App setup: manual installation and task-specific configuration are required.
- Compatibility note: the original AndroidLab Docker images are not compatible with AVD environments.
# one task
python eval.py -n all_cloud_v1_hyper -c ./configs/example_xml_cloud_hyper.yaml --task_id zoom_1

# several tasks
python eval.py -n all_cloud_v1_hyper -c ./configs/example_xml_cloud_hyper.yaml --task_id zoom_1 clock_1

# every task in the config (omit --task_id)
python eval.py -n all_cloud_v1_hyper -c ./configs/example_xml_cloud_hyper.yaml
Batch scripts live in test_script/:
all_test_cloud_v1_hyper.sh — all 138 AndroidLab benchmark tasks.all_test_cloud_v1_hyper_add.sh — tasks for four additional mobile apps.
Beyond the 138 AndroidLab tasks, the repository ships 25 additional tasks across four more mobile apps (Chrome, Gmail, TikTok, Reddit) — see Additional Apps Documentation.
The Android side of the harness ships compiled app maps and its own runner in phonecli_android/: 9 apps / 138 tasks, one map per app, plus the pure-VLM baseline used for the comparison below.
Our implementation replaces AndroidLab's rule-based evaluation with LLM-powered assessment, which is more nuanced about partial success.
Configure credentials in evaluation/tasks/llm_evaluator.py (line 10: API configuration; line 12: service URL), then generate results:
python generate_result.py --input_folder ./logs/evaluation/ --output_folder ./logs/evaluation/ --output_excel ./logs/evaluation/test_name.xlsx
⚠️ When using the batch scripts, move the generated evaluation files from the script directory into ./logs/ first, then run the command above — this avoids file-path conflicts.
Ablation over the nine AndroidLab apps: the full harness, the harness without replay (app maps but no deterministic execution), and without app maps (pure VLM). Compilation is what moves the needle — with both the map and replay the agent solves more tasks while spending fewer steps and fewer tokens per success (6.72 vs 7.52 steps, 34.4k vs 40.1k tokens).
🏆 Small model, big performance
- Size vs performance: OpenPhone-3B reaches the range of 9B models while keeping the deployment advantages of a compact architecture.
- Efficiency champion: a genuine "small powerhouse" that challenges the bigger-is-better assumption in mobile AI.
🥊 Competitive performance
- Against proprietary models: respectable results compared with lightweight versions of proprietary models on standard benchmarks.
- Potential of small models: validates compact, open-source approaches for mobile agents.
🔄 The execution tiers work
- Performance with efficiency: the hybrid architecture keeps near-optimal performance while cutting cloud usage.
- Intelligent routing: smart task routing produces practical savings without sacrificing capability.
🧠 Longer prompts don't always help
- Context matters: extended prompting only pays off when paired with a sufficiently capable cloud model.
- Smart matching: match reasoning complexity to model capability rather than assuming longer prompts always help.
If you find this work helpful to your research, please kindly consider citing our paper.
@article{jiang2026phonecli,
  title={PhoneCLI: From App Interfaces to Callable Commands for Mobile Agents},
  author={Jiang, Yangqin and Xu, Lingrui and Huang, Chao},
  journal={arXiv preprint arXiv:2609.35671},
  year={2026}
}

@inproceedings{jiang2026openphone,
  title={OpenPhone: Mobile Agentic Foundation Models},
  author={Jiang, Yangqin and Huang, Chao},
  booktitle={Findings of the Association for Computational Linguistics: ACL 2026},
  pages={30362--30380},
  year={2026}
}
OpenPhone builds upon excellent open-source projects. We sincerely thank their authors and contributors:
- AndroidLab - The benchmark framework.
- R1-V - Implementation details for the GRPO training methodology.
- LLaMA Factory - The unified training framework enabling efficient model fine-tuning.
This project is released under the MIT License.
If this project helps you, please give us a Star🌟
🤖 Empower AI Phone with Agents!
❤️ Thanks for visiting ✨ OpenPhone!